Grouped Value Attention
An attention variant that caches grouped values and reconstructs content keys on demand via a learned linear map absorbed into the query, cutting persistent KV cache by ~45-47% versus GQA with near-GQA accuracy
Read Paper →Here you'll find information about me, my research, how to get in touch, and testimonials.
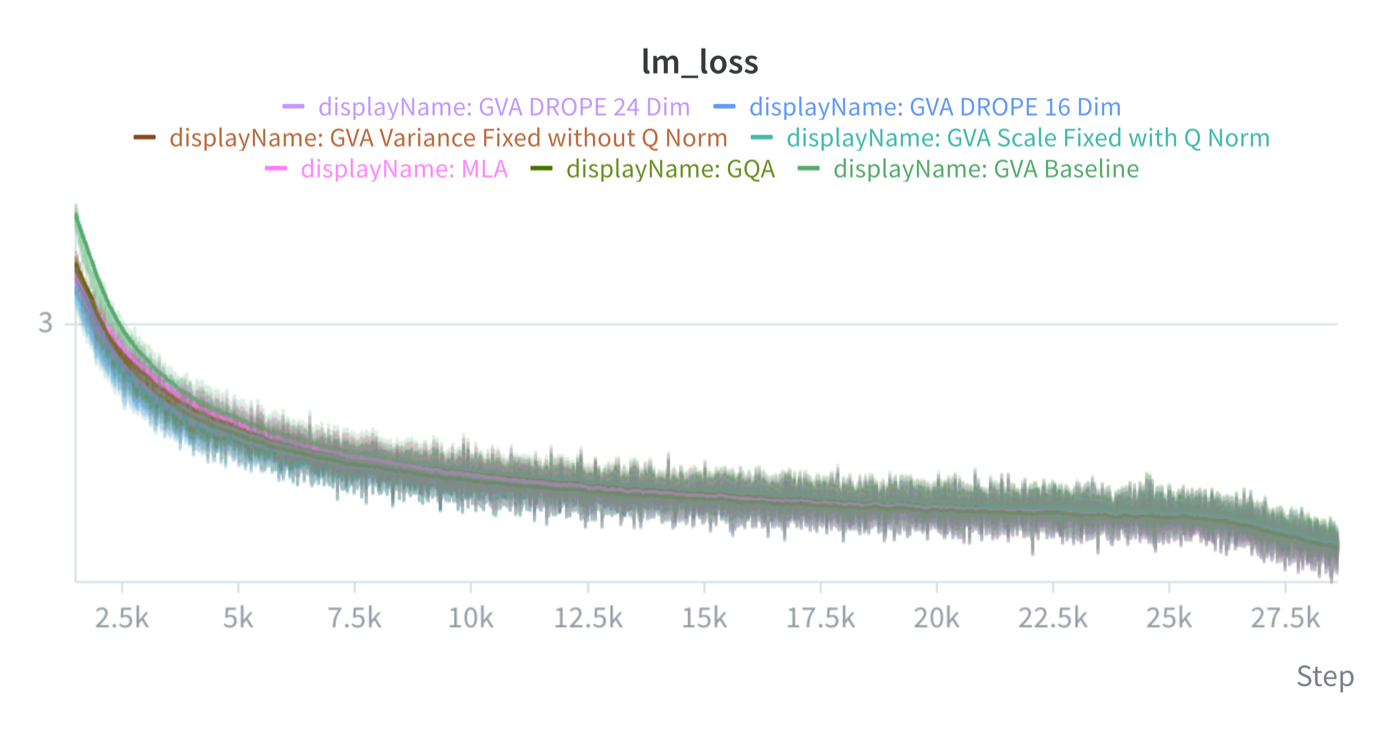
An attention variant that caches grouped values and reconstructs content keys on demand via a learned linear map absorbed into the query, cutting persistent KV cache by ~45-47% versus GQA with near-GQA accuracy
Read Paper →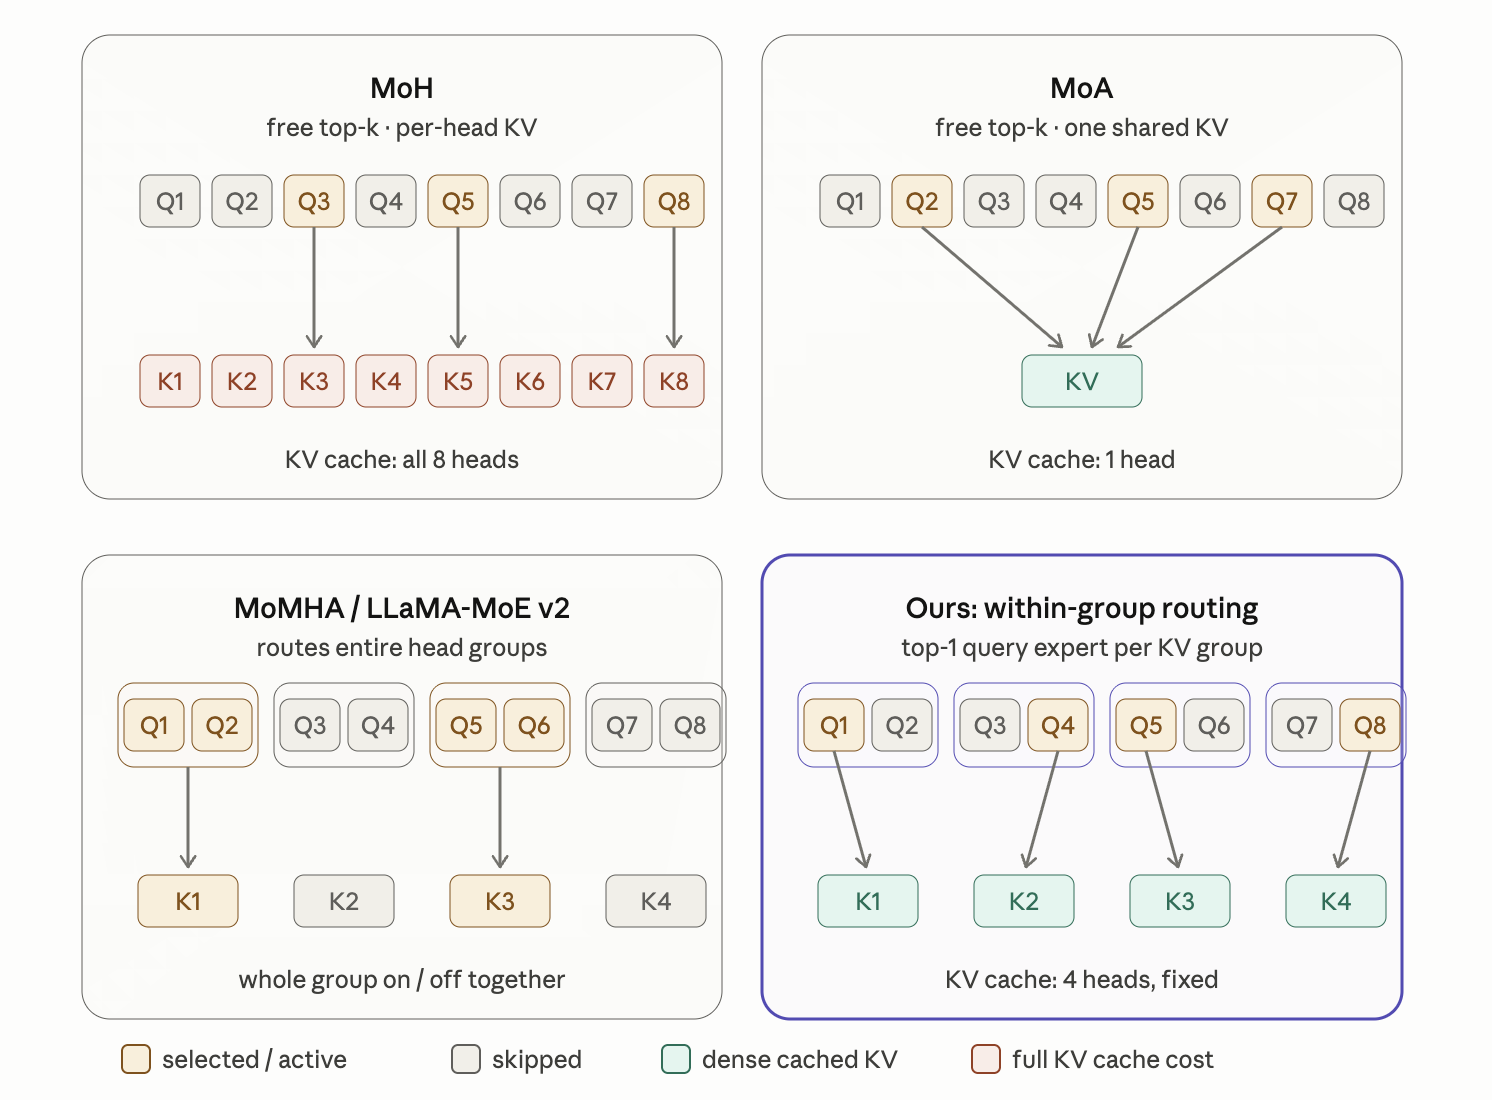
A mixture-of-experts layer on grouped-query attention that routes each token to a subset of query-head experts while keeping KV heads dense, matching GQA accuracy with half the query heads active and 1.7-1.8x faster long-context prefill
Read Paper →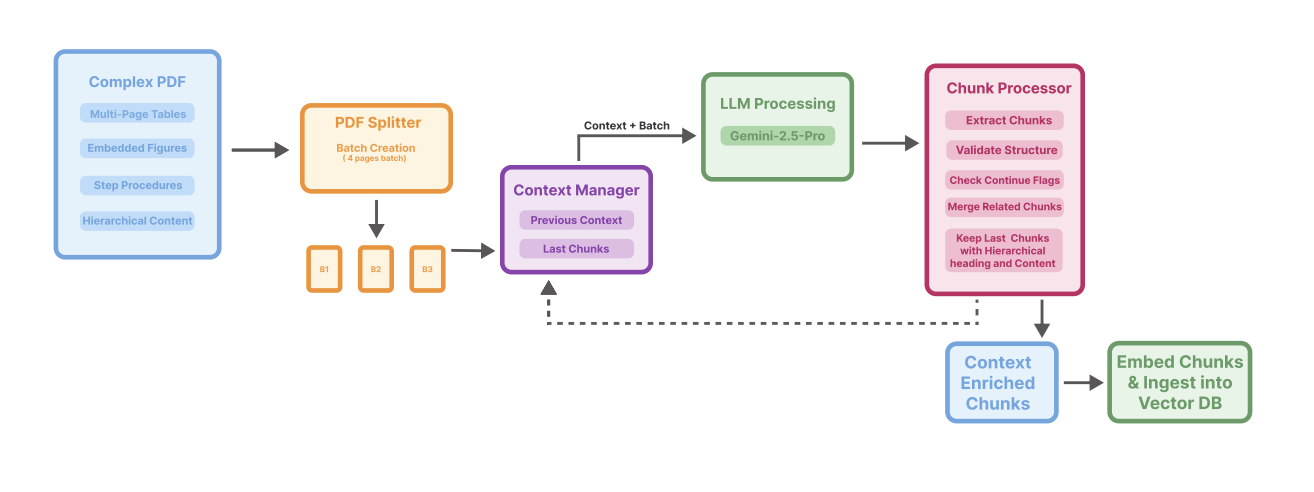
A novel multimodal document chunking approach that leverages LMMs to process PDF documents in batches while maintaining semantic coherence and structural integrity
Read Paper →
Large Language Models designed to address this gap by seamlessly operating across Indonesian, English, and 11 regional languages in Indonesia
Read Paper →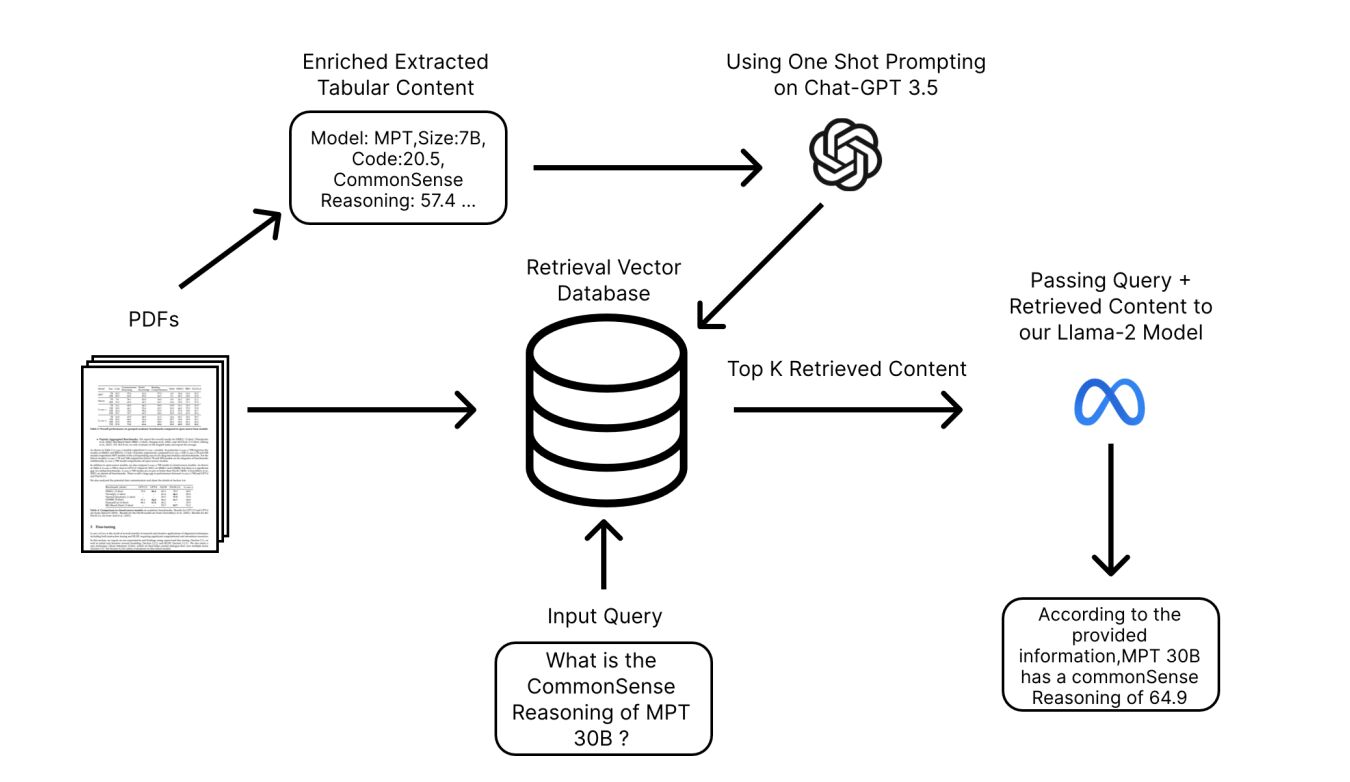
This research introduces an innovative approach to enhance the accuracy of complex table queries in RAG-based systems
Read Paper →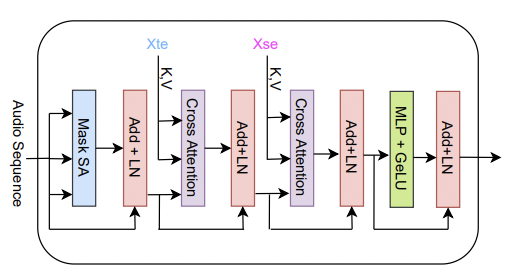
This research introduces a comprehensive Bahasa text-to-speech (TTS) dataset and a novel TTS model, EnGen-TTS, designed to enhance the quality and versatility of synthetic speech in the Bahasa language
Read Paper →I had the pleasure of supervising Vishesh during his internship at Yellow.ai NLP Research team, and I can confidently say that he is a highly talented and dedicated individual. Vishesh quickly grasped complex concepts and demonstrated a strong passion for AI. Throughout his internship, Vishesh consistently delivered high-quality work, showing a keen attention to detail and a proactive approach to problem-solving.
Vishesh is an exceptional talent! His ability to execute tasks swiftly and efficiently, coupled with his strong analytical skills, made him a valuable asset during his internship. I highly recommend Vishesh for any role where dedication and proactive problem-solving are valued.
One of the most self-motivated people I know who wants to learn and apply everything there is about AI-ML. I have known him since he started his learning journey and he is someone you do not need to ask again and again to get things done in the right way with the right approach. He looks technical but he can easily solve any Non-technical problem as well through his structured problem-solving approach.
Had the pleasure of working closely with Vishesh on multiple projects during our time together at Yellow.ai. Vishesh played a key role in advancing our TTS system while simultaneously contributing significantly to our in-house LLM, Komodo. His dedication, technical expertise, and collaborative spirit were instrumental in driving both projects forward.We also had the opportunity to co-author a research paper on our novel in-house TTS system, which has been accepted at EMNLP 2025.